 ⚡ Systems & Architecture
The Observable Kernel Systems Engineering Moves Closer to Production Reality
Kernel-level signals, safer components and tighter feedback loops help teams understand performance without drowning in telemetry.
100%
 ⚡ Systems & Architecture
Kernel-level signals, safer components and tighter feedback loops help teams understand performance without drowning in telemetry.
The best architecture is not the most distributed. It is the one that lets teams change important parts safely and recover quickly.
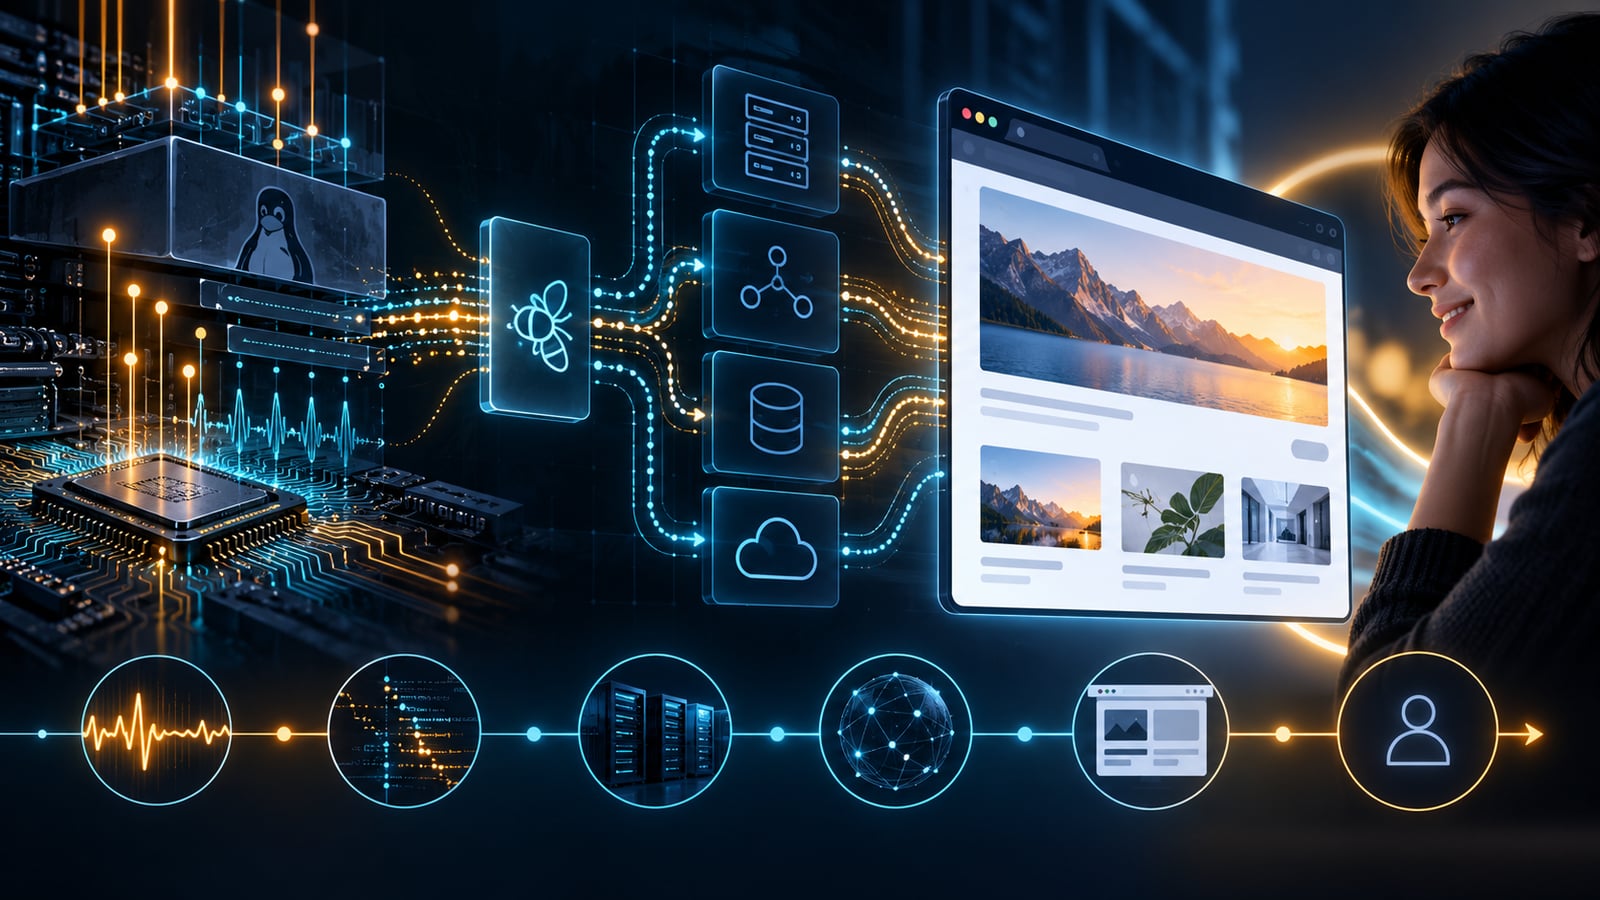
Systems engineering in 2026 is increasingly defined by visibility. Distributed applications fail across layers: a slow user request may begin in browser code, cross several services, wait on storage and finally expose contention in the operating system. Logs from individual components cannot explain that full path.
Kernel-level observability, including eBPF-based instrumentation, helps teams inspect networking, scheduling and system calls with less friction than traditional invasive tracing. Collecting everything is not the goal. Useful observability begins with questions: where is latency introduced, which dependency is saturated and what changed?
Architecture must connect signals to user impact. Trace and metric conventions should follow requests across process boundaries. High-cardinality detail should be sampled intentionally, and retention should reflect investigative value. Telemetry also needs protection because traces can contain identifiers and sensitive context.
The larger trend is a tighter loop between design and operations. Performance budgets, load tests, fault injection and production telemetry should influence architecture continuously. Systems become understandable when engineers can move from a user symptom to the responsible resource without guesswork.
What engineering teams should do now
Sources and further reading
Comments0