TypeSafe AI's Jev does not want to write your email, explain quantum mechanics or generate an application. It wants to answer a smaller question quickly: given this state, which bounded decision should software make next?
A practical framework for deciding when off-the-shelf models have reached their limit—and when your data, economics, and constraints justify building your own.
A practical loop for keeping AI agent evals fresh: capture production traces with outcome labels, curate the failures worth testing, convert them into property-based eval cases, and verify fixes against both evals and production failure rates.
That makes Jev interesting for AI engineering—not because it replaces large language models, but because it challenges an expensive habit: using a general-purpose text generator for every decision inside an agent loop.
An agent may repeatedly ask:
Which tool should I call?
Is the task complete?
Is this response safe to send?
Which queue owns this ticket?
Should I retry?
Does this output contradict the supplied record?
Those are not essay-writing problems. They are bounded decisions. The valid answers are often known in advance; the system needs a useful probability distribution and a confidence signal.
TypeSafe calls Jev a System One Model, borrowing from the fast-thinking side of Daniel Kahneman's distinction. Its public interface supports three question forms:
Noul — a yes-or-no proposition returned as a probability;
Choice — a selection among predefined options;
Score — a position on an ordered scale.
The result is not prose to parse. It is a bounded value code can inspect.
Why Text Generation Is Expensive Inside a Loop
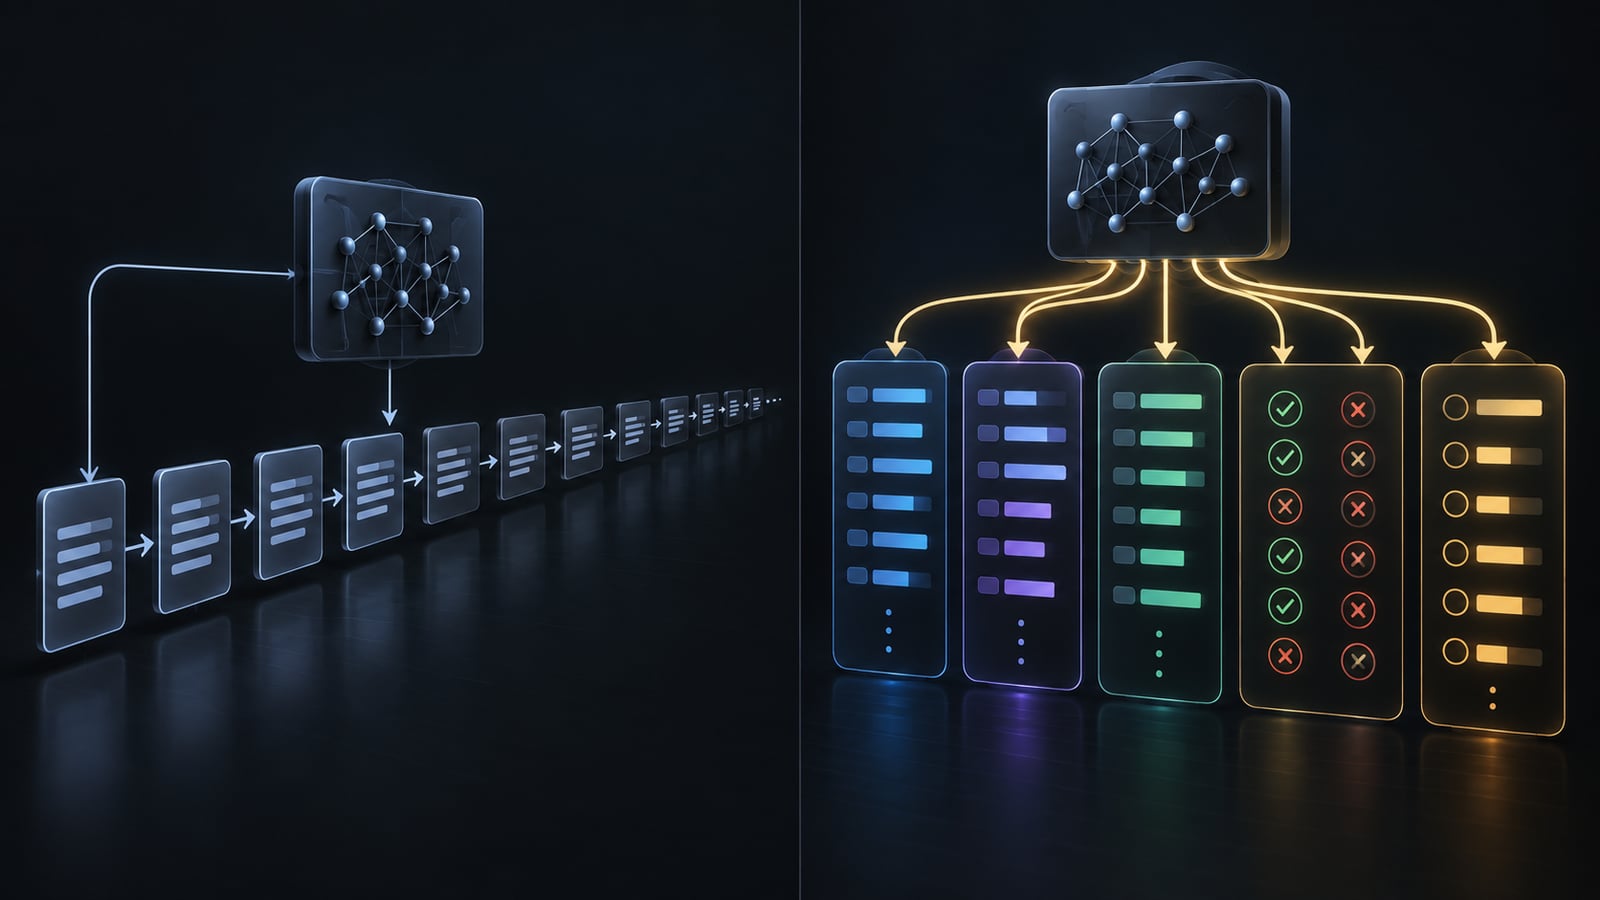
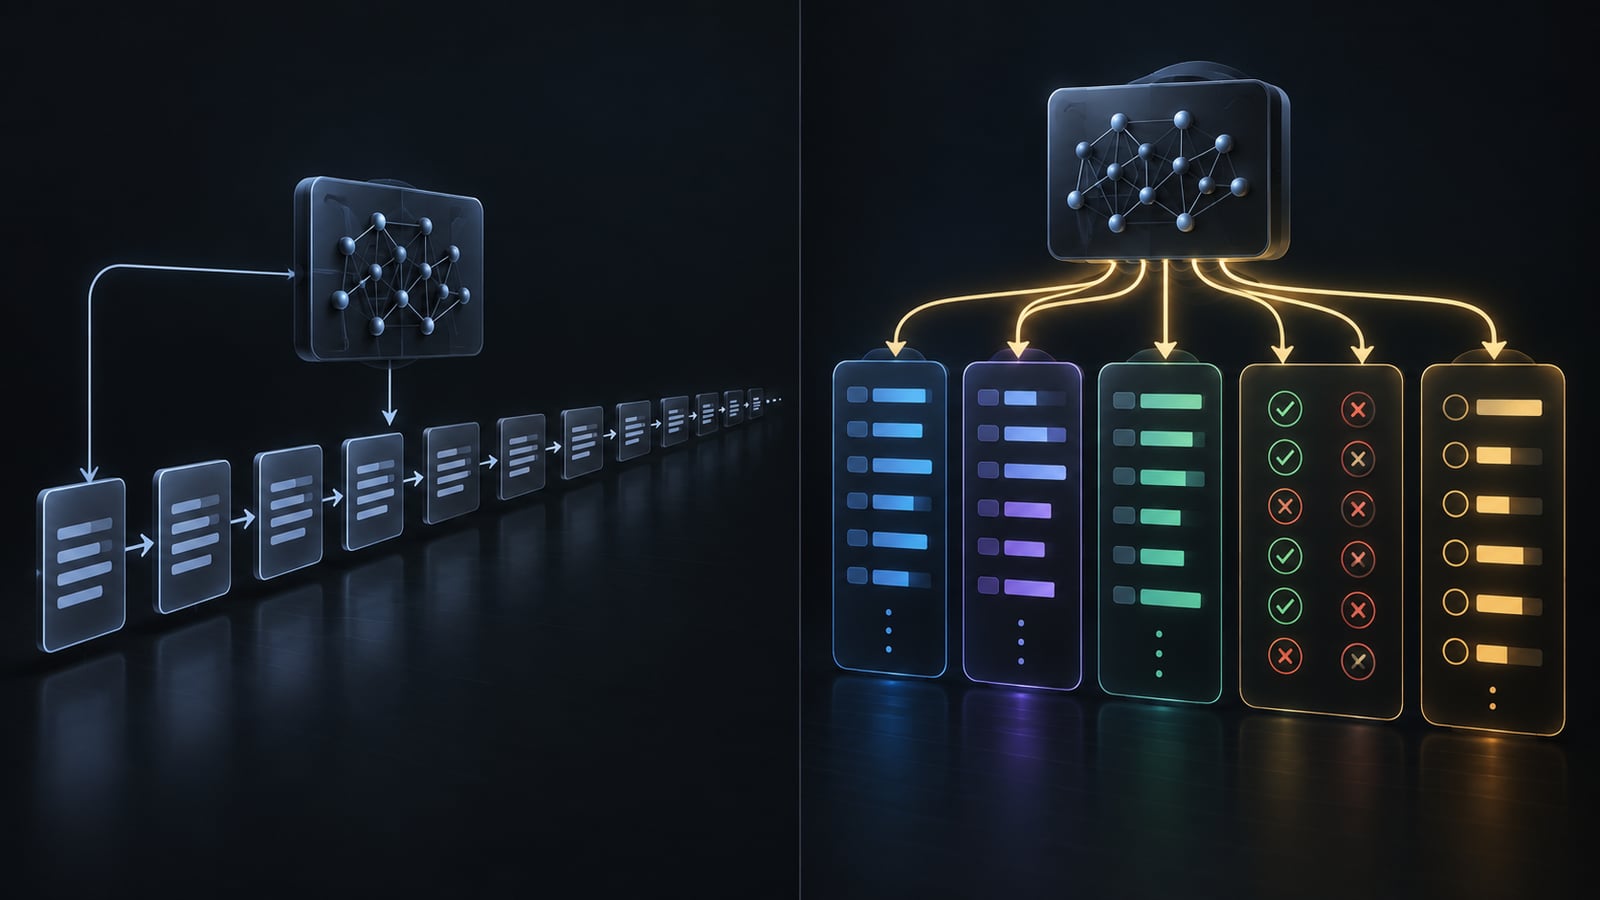
Autoregressive language models generate output token by token. That is valuable when the product is text, code or a plan. It is wasteful when the product is one of four routing labels.
Modern structured-output APIs can constrain an LLM to JSON:
That is much better than extracting JSON from prose. But the underlying model still performs text generation, and a multi-step agent pays the latency and cost at each branch.
Jev takes a different path. Possible answers are defined before inference, and multiple questions about one state are evaluated in parallel.
TypeSafe reports roughly 70–500 ms end-to-end latency and input pricing of $0.042 per million tokens, with output too small to meter. It also reports large speed and cost advantages in its workflow evaluations. These are company-published measurements, not universal guarantees. TypeSafe notes caveats: short dense inputs can favour Jev, workflow evals use frontier models as reference probabilities, and headline gains represent the favourable end of observed workflows. Benchmark your own traffic.
The Interface Is the Product
A request contains one shared state and several bounded questions:
text
{ "model": "jev-latest", "state": { "message": "My payouts have failed for three days. I am losing sales.", "customer_tier": "business", "open_incidents": ["payments-api-degraded"] }, "questions": { "is_urgent": { "type": "noul", "instructions": "The issue requires time-sensitive handling" }, "department": { "type": "choice", "instructions": "Select the team that should own the next action", "criteria": { "billing": "Invoices, charges, refunds and settlement", "technical": "Bugs, outages and integrations", "sales": "Pricing, upgrades and new accounts" } }, "impact": { "type": "score", "instructions": "Estimate operational impact", "criteria": ["low", "medium", "high", "critical"] } }}
The key engineering work is decomposition:
one state describes one case;
each question asks for one decision;
each answer space is bounded;
criteria define what every option means;
code owns the action after inference.
“Handle this customer” is not a decision contract. It bundles diagnosis, routing, writing and authorization into one opaque instruction. Jev is strongest when engineers can state what software needs to know next.
Calling Jev From a Cloudflare Worker
Cloudflare exposes Jev as typesafe/jev in Workers AI:
text
export interface Env { AI: Ai;}type Ticket = { message: string; customerTier: "free" | "pro" | "business"; ageMinutes: number;};export async function evaluateTicket(env: Env, ticket: Ticket) { return env.AI.run("typesafe/jev", { state: ticket, questions: { is_urgent: { type: "noul", instructions: "Does this require time-sensitive handling?", criteria: { true: "Revenue loss, outage, security impact or explicit deadline", false: "No immediate operational or time-sensitive impact", }, }, department: { type: "choice", instructions: "Which team should own the next action?", criteria: { billing: "Invoices, charges, refunds and settlement", technical: "Bugs, outages and integrations", sales: "Pricing, upgrades and new accounts", }, }, impact: { type: "score", instructions: "Estimate customer impact", criteria: ["low", "medium", "high", "critical"], }, }, });}
Validate the exact response against the current SDK types. More importantly, do not wire it directly to a side effect. Put deterministic policy between prediction and action.
This is the actual pattern: not an autonomous employee, but a cheap probabilistic branch inside ordinary code.
Calibration Matters More Than Confidence
A confidence value is useful only when calibrated. If a model assigns approximately 0.8 probability to one hundred comparable decisions, about eighty should be correct.
A model that says 0.99 whenever it feels strongly but is correct only 75% of the time is not automation-ready, even if top-line accuracy is good.
Calibration is local to task and distribution. A model may be calibrated for English support tickets and poorly calibrated for mixed Telugu-English messages, terse logs or institution-specific abbreviations.
text
from collections import defaultdictdef calibration_bins(predictions, labels, width=0.1): bins = defaultdict(list) for probability, label in zip(predictions, labels): lower = int(probability / width) * width bins[round(lower, 1)].append((probability, label)) report = [] for lower, items in sorted(bins.items()): mean_confidence = sum(p for p, _ in items) / len(items) observed_accuracy = sum(bool(y) for _, y in items) / len(items) report.append({ "range": f"{lower:.1f}-{min(lower + width, 1.0):.1f}", "count": len(items), "mean_confidence": round(mean_confidence, 3), "observed_accuracy": round(observed_accuracy, 3), "gap": round(abs(mean_confidence - observed_accuracy), 3), }) return report
Evaluate each high-value question separately. “Urgent” and “safe to execute” have different costs. One threshold is rarely enough.
Build a Three-Way Decision Gateway
A robust integration has three outcomes:
1. Act when the case is within the evaluated domain and above threshold. 2. Review when evidence is ambiguous or the error cost is meaningful. 3. Fallback when the service fails, input is unsupported or policy forbids automation.
Confirm the provider's exact semantics for probability and confidence before implementing the gate. A plausible field name is not an API contract.
Where Jev Fits Beside an LLM
Use a generative model when the system must write a response, explain evidence, produce code, synthesize documents or create an open-ended plan.
Use a bounded decision model when it must route, classify, score severity, approve a low-risk tool call, decide whether to retry, detect contradictions, judge completion or select from known candidates.
A hybrid loop can reserve expensive generation for the parts that require it:
text
async function runAgent(task: Task) { const plan = await reasoningModel.createPlan(task); for (const step of plan.steps) { const approval = await jev.evaluate({ state: { task, step }, questions: { can_execute: { type: "noul", instructions: "This step is specified and low-risk", }, }, }); if (approval.can_execute.noul < 0.90) { return requestHumanReview({ task, step, approval }); } const toolResult = await executeBoundedTool(step); const status = await jev.evaluate({ state: { step, toolResult }, questions: { outcome: { type: "choice", instructions: "Classify the result", criteria: { complete: "The intended outcome was achieved", retryable: "One transient retry is reasonable", blocked: "Information or policy prevents progress", }, }, }, }); if (status.outcome.choice === "retryable") await retryOnce(step); else if (status.outcome.choice !== "complete") { return requestHumanReview({ task, step, status }); } }}
Keep retries deterministic and bounded. Cheap decisions are not permission for infinite micro-decisions.
“Cannot Hallucinate” Needs a Precise Reading
TypeSafe says Jev cannot hallucinate because it cannot emit values outside the declared type. That is a useful guarantee about output space.
It does not mean the model cannot choose the wrong valid option.
If departments are billing, technical and sales, Jev will not invent “quantum escalations.” It can still route billing to technical. Type safety removes one failure class; it does not establish semantic correctness.
Classification errors are quieter than absurd prose. They appear as tickets in the wrong queue, legitimate accounts flagged as risky, retries after permanent failures or confident but incorrect approvals. These require labelled data, monitoring and thresholds—not just a parser.
Run a Private Evaluation
Build a dataset from your traffic. For every case record the state, expected decision, probability and confidence, latency, token count, cost, gate result and downstream outcome.
text
def automation_report(rows):
    autonomous = [r for r in rows if r["gate"] == "act"]
    reviewed = [r for r in rows if r["gate"] == "review"]
    wrong = [r for r in autonomous if r["prediction"] != r["expected"]]

    return {
        "coverage": len(autonomous) / len(rows),
        "autonomous_accuracy": (
            1 - len(wrong) / len(autonomous) if autonomous else 0
        ),
        "review_rate": len(reviewed) / len(rows),
        "total_cost_usd": sum(r["cost_usd"] for r in rows),
    }
The central trade-off is coverage versus error. Raising thresholds reduces autonomous volume but usually improves accuracy. The correct operating point depends on the cost of error and capacity of the review queue.
Production Checklist
Define one narrow question per decision.
Write criteria that domain experts agree on.
Redact sensitive state.
Keep provider credentials server-side.
Pin model or gateway configuration where possible.
Evaluate on private representative examples.
Measure calibration by question and segment.
Implement act, review and fallback paths.
Cap retries and total calls.
Log decisions, thresholds and policy outcomes.
Keep a deterministic or human fallback.
Canary changes before full rollout.
During an outage, a support router may fall back to a general queue. A fraud control may fail closed or escalate. Reliability policy belongs to the application, not the model.
The Bigger Idea
Jev's most important contribution may be the argument that machine intelligence needs interfaces designed for software rather than conversation.
LLMs made intelligence accessible through language, but many production decisions are narrower. Their answer spaces are known. Their uncertainty can be measured. Their consequences can be gated in code.
The intelligence is probabilistic. The control remains explicit.
If Jev's reported economics hold on real workloads, teams will place more small decisions throughout software. That is the Jevons-paradox bet behind its name: cheaper intelligence produces more consumption of intelligence. The opportunity is substantial—and so is the need for calibration, observability and restraint.
The right conclusion is neither “Jev replaces LLMs” nor “Jev is just a classifier.” It is a specialized primitive for bounded decisions. Its value depends on how carefully engineers choose those decisions and how safely code turns probabilities into action.
 🧠 AI & Machine Learning
Comments0