 🧠 AI & Machine Learning
AI Search Is Moving Work Out of the Request Path
Retrieve-for-Train suggests a practical design shift: learn repeatable search behavior offline, but keep live facts and permissions online.
100%
🧠 AI & Machine LearningRetrieve-for-Train suggests a practical design shift: learn repeatable search behavior offline, but keep live facts and permissions online.
A practical framework for deciding when off-the-shelf models have reached their limit—and when your data, economics, and constraints justify building your own.
A practical loop for keeping AI agent evals fresh: capture production traces with outcome labels, curate the failures worth testing, convert them into property-based eval cases, and verify fixes against both evals and production failure rates.
Persistent memory is becoming an infrastructure feature. The harder problem is deciding what an agent may remember, trust, update, and forget.
A search box is a strange place to make a model rediscover the same strategy thousands of times.
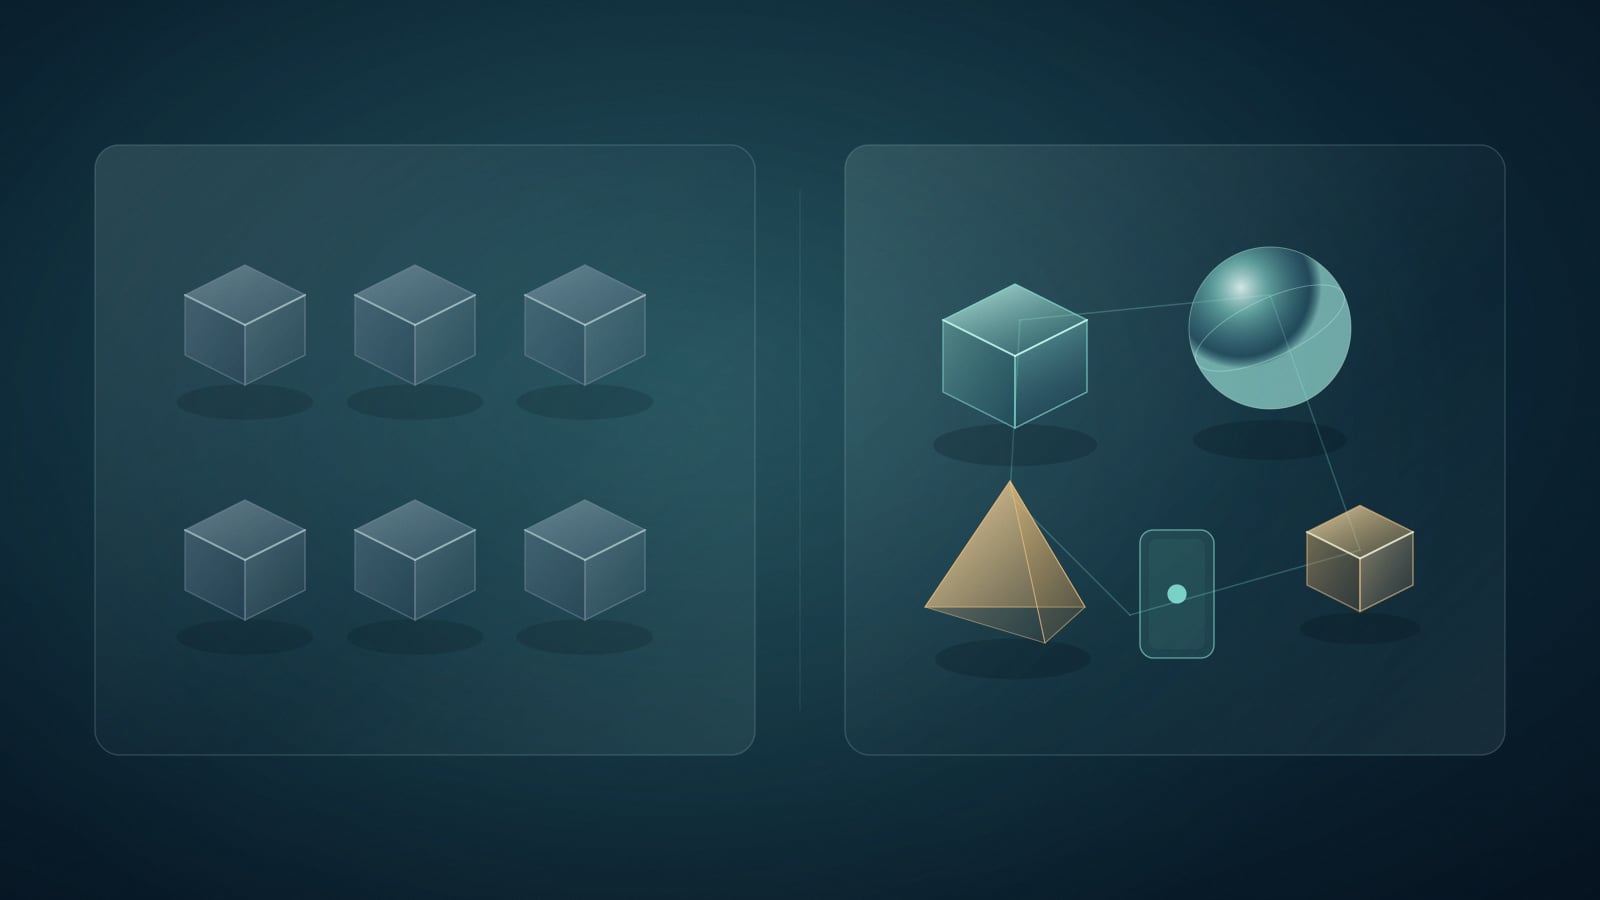
Consider an internal developer portal. An engineer searches for a “production-ready event-driven starter.” A useful result set might contain a service template, an event contract, a retry pattern, an observability example, and an operational runbook. Five near-identical service templates would miss the point, even if each one looked highly relevant in isolation.
This is an illustrative workload, not a production benchmark. Its design problem is real: the system must optimize the usefulness of the collection, not merely the score of each document.
On September 15, 2026, Google Research highlighted Retrieve-for-Train, or R4T, a method for moving expensive query-expansion work into offline training. The underlying paper was first submitted on March 6, 2026; the September publication is a fresh engineering explanation, not the paper's original release. [1][2]
The interesting question is not whether every search service should train a diffusion model. It is this: which decisions are worth learning once, rather than reasoning through again on every request?
The useful unit is the whole result set
For the portal example, start by defining what a successful collection must accomplish. It should cover the stages of building and operating a service, avoid near-duplicates, and remain relevant to the engineer's stack. Every returned document must also be current enough to use and accessible to that engineer.
Treat the last requirement as a gate, not a preference. A highly relevant document that the caller cannot access is not a slightly worse result. It is an ineligible result.
This distinction separates a product objective from a ranking shortcut. Diversity is helpful when a user needs complementary resources. It can be distracting when the request is for one exact error code or a particular document revision. Route those cases differently rather than forcing the same diversity setting onto every query.
What Retrieve-for-Train changes
R4T uses a three-stage process. First, reinforcement learning trains a language model to expand a broad query into useful subqueries. Next, the trained model generates query-and-target-set examples offline. Finally, a compact diffusion retriever learns from those examples and produces target embeddings at query time, rather than generating a long sequence of textual subqueries. [1]
In the authors' fashion and music experiments, the 53.9-million-parameter diffusion model delivered roughly 12-20 times lower fan-out generation latency than the autoregressive comparison. That is a result for a particular stage and experimental setup—not evidence that an entire search application becomes 12-20 times faster. [2]
There is another detail worth preserving. “Non-autoregressive” does not mean computation-free, or necessarily one neural-network evaluation. The paper's implementation appendix lists 256 diffusion steps. Use the measured configuration when discussing speed, rather than turning “single-pass fan-out” into a universal claim about the number of model calls. [2]
My engineering takeaway is narrower than the headline: repeated, domain-specific search behavior is a candidate for offline specialization. The surrounding service still has to retrieve real records and apply current constraints.
Try the cheaper baseline first
Before adding an offline training pipeline, establish whether a simpler reranker solves the problem.
Maximum marginal relevance, or MMR, balances a candidate's relevance against its similarity to results already selected. Elastic's engineering explanation shows how this approach can diversify an otherwise repetitive result list. It is a useful baseline—not the same method as R4T and not a substitute for learning a genuinely complex set objective. [3]
Here is a small, dependency-free implementation. It assumes that candidate IDs have already passed authorization and availability checks, and that both scoring functions return comparable values between zero and one. Choose the weight through evaluation; there is no universally correct setting.
from collections.abc import Callable, Mapping, Sequence
from math import isfinite


def select_diverse(
    ids: Sequence[str],
    relevance: Mapping[str, float],
    similarity: Callable[[str, str], float],
    *,
    k: int,
    weight: float,
) -> list[str]:
    """Select up to k IDs. All relevance/similarity scores must be in [0, 1]."""
    if k < 0 or not isfinite(weight) or not 0 <= weight <= 1:
        raise ValueError("k must be nonnegative; weight must be in [0, 1]")

    def checked(score: float) -> float:
        if not isfinite(score) or not 0 <= score <= 1:
            raise ValueError("scores must be finite and in [0, 1]")
        return score

    pool = list(dict.fromkeys(ids))
    scores = {item: checked(relevance[item]) for item in pool}
    chosen: list[str] = []
    while pool and len(chosen) < k:
        def utility(item: str) -> float:
            redundancy = max(
                (checked(similarity(item, prior)) for prior in chosen),
                default=0.0,
            )
            return weight * scores[item] - (1 - weight) * redundancy

        winner = max(pool, key=utility)
        chosen.append(winner)
        pool.remove(winner)
    return chosen
This code cannot recover a missing facet if the candidate pool never contained it. It also does not enforce compatibility between components. For the portal workload, explicitly test whether the selected template, contract, and retry example belong to compatible versions. “Different” and “works together” are not equivalent objectives.
Keep the changing world on the live path
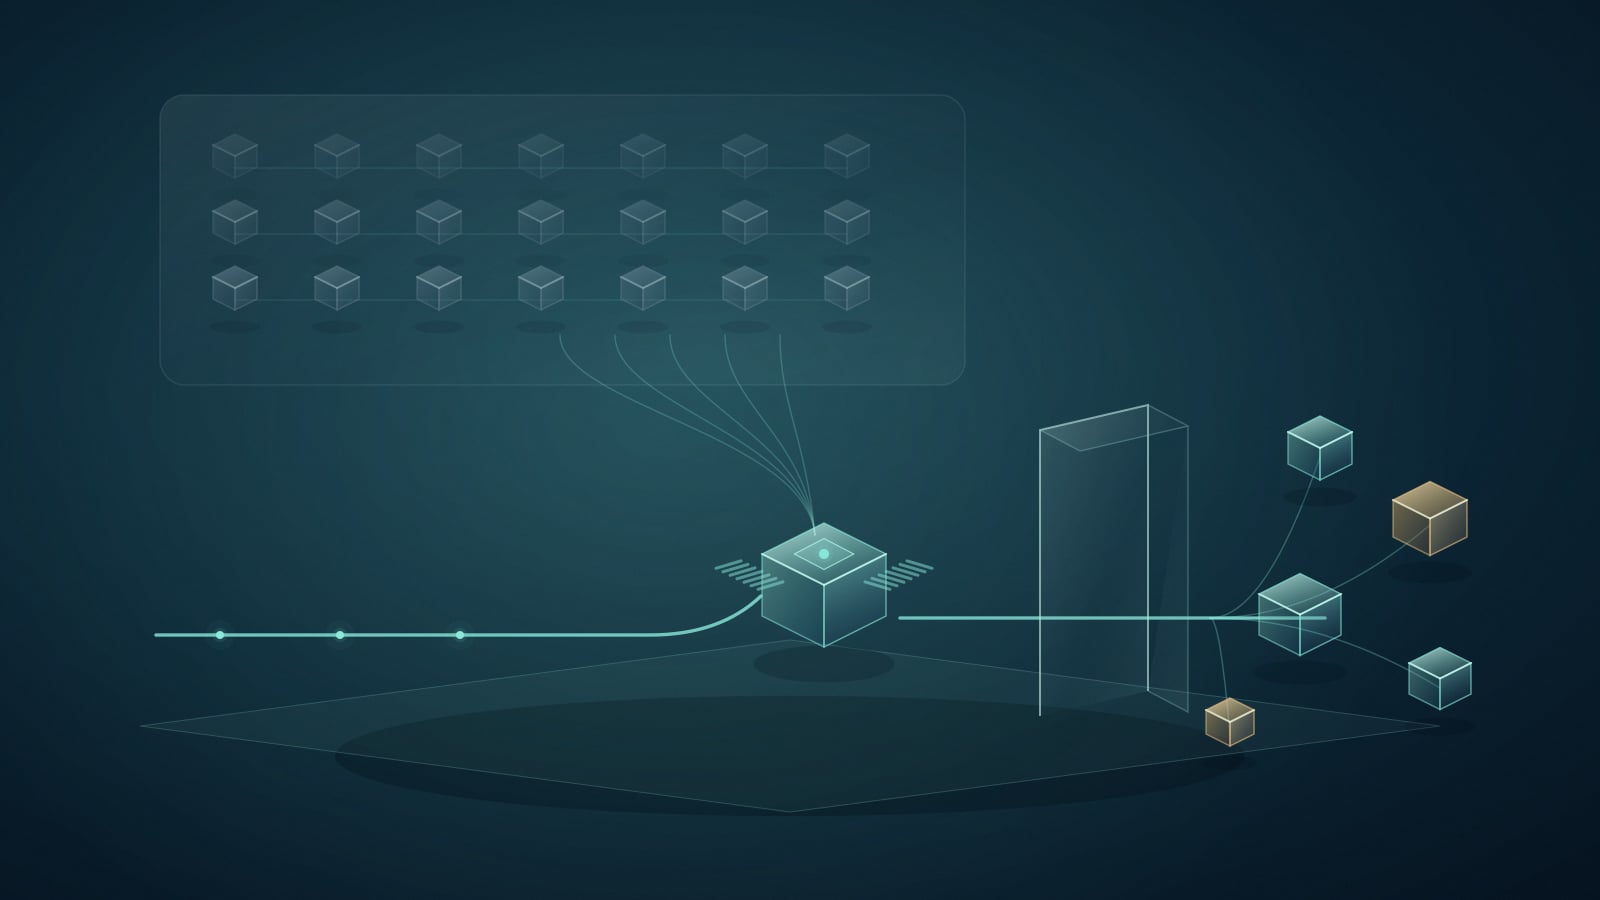
For a first experiment, I would separate the system into an offline learning path and a live eligibility path.
The offline path would contain de-identified training queries, a versioned corpus snapshot, explicit collection-quality criteria, and held-out evaluation cases. Only add a specialized model after measuring the simpler baseline. Freeze the evaluation set before tuning either approach.
On the live path, authenticate the caller, search within the authorized corpus, retrieve candidate IDs, check current eligibility, and rerank the survivors. Revalidate access before rendering the response. Never let a model's learned association stand in for the access-control service or the source of truth about whether a resource still exists.
If filtering removes an important facet, refill from authorized candidates or return a smaller, honest collection. Do not silently widen permissions to restore the desired result count. Put limits on refilling and retries so that the fallback cannot consume the latency budget it was meant to protect.
Measure the service, not just the model
For a pilot, compare ordinary retrieval, retrieval with MMR-style reranking, online language-model fan-out, and the specialized approach. Use the same authorized corpus snapshot and result-count policy. Include exact-match queries, broad requests, newly added documents, and permission changes.
Report collection quality alongside end-to-end latency. Useful measurements include intent coverage, duplicate rate, compatibility failures, inaccessible-result rate, and task completion. Record p50, p95, and p99 latency with workload and concurrency details. Break the total into query processing, retrieval, eligibility checks, reranking, and any retries.
For economics, use a consistent evaluation window:
break-even requests = extra offline cost / per-request savings
As an illustration, not measured R4T pricing—an additional $800 of preparation and refresh cost, with $0.008 saved per request, breaks even at 100,000 requests. Include unsuccessful requests, idle serving capacity, maintenance, and human review on the appropriate side of the comparison. If per-request savings are zero or negative, there is no cost break-even from traffic alone.
The same discipline applies to speed. If fan-out consumes 40% of baseline latency, making only that stage 20 times faster leaves 62% of the original total: 0.60 + 0.40 / 20 = 0.62. Under those simplified assumptions, the end-to-end improvement is about 1.61 times, not 20 times. These are illustrative calculations, not experimental results.
The decision to make
Favor offline specialization when the query distribution repeats, the collection-quality objective is stable enough to evaluate, and traffic justifies maintaining a training pipeline. Keep online reasoning where tasks are novel, constraints change frequently, or the system needs fresh exploration.
For a first deployment, start with the smallest change that tests the hypothesis: a better candidate pool, an explicit set-quality evaluation, and a diversity-aware reranker. Specialize only after identifying a remaining bottleneck.
The goal is not to eliminate reasoning. It is to stop paying for the same reasoning repeatedly when a smaller, evaluated component can do the job.
Sources and further reading
[1] Google Research. “Bypassing inference bottlenecks: Accelerating complex AI search with Retrieve-for-Train.” September 15, 2026. https://research.google/blog/bypassing-inference-bottlenecks-accelerating-complex-ai-search-with-retrieve-for-train/
[2] Jiang et al. “Efficient, Property-Aligned Fan-Out Retrieval via RL-Compiled Diffusion.” arXiv:2603.06397, version 1, March 6, 2026. See Section 3.4 and Appendix F for the efficiency configuration. https://arxiv.org/html/2603.06397v1
[3] Elastic Search Labs. “Diversifying search results with Maximum Marginal Relevance.” https://www.elastic.co/search-labs/blog/maximum-marginal-relevance-diversify-results
Comments0