 🤖 AI Engineering
AI Engineering Is Reliability Engineering for Probabilistic Systems
An LLM demo can be built in an afternoon. A system that uses an LLM safely, economically and repeatedly under production traffic is a different discipline.
100%
 🤖 AI Engineering
An LLM demo can be built in an afternoon. A system that uses an LLM safely, economically and repeatedly under production traffic is a different discipline.
The hard part is rarely the first model call. It is everything after that call works: retrieving correct context, constraining tool access, validating outputs, controlling cost, tracing decisions, testing changes and deciding when software must stop and ask a person.
That is why an impressive Friday prototype can still be six months from a dependable product. The prototype proves a model can sometimes perform the task. Production engineering must show that the whole system behaves acceptably across ordinary cases, ambiguity, adversarial inputs, dependency failures and model upgrades.
The useful mental model is:
“An AI feature is a distributed system with a probabilistic component inside it.”
Once you accept that, the priorities become familiar: define contracts, isolate failure, limit privilege, measure behaviour, test recovery and expose uncertainty.
Most production AI systems contain at least six layers:
1. Input boundary — authenticates callers and validates payloads. 2. Context layer — retrieves records or documents under access rules. 3. Model layer — classifies, extracts, plans or generates. 4. Tool layer — exposes bounded actions. 5. Policy layer — determines what may execute and what needs review. 6. Observability layer — records traces, versions, latency, cost and outcomes.
Failures occur at the joins. Retrieval returns an obsolete policy. A tool description is ambiguous. A retry duplicates an action. A model upgrade changes tool selection. A trace captures private data.
Calling every failure “hallucination” conceals the engineering work. The better question is: which boundary allowed a wrong prediction to become a harmful action?
Free-form text is useful at the interface. It is a poor internal protocol. Convert model output into a small schema before business logic sees it, then validate it like data from an untrusted external service.
import { z } from "zod";

const Decision = z.object({
  intent: z.enum(["refund_request", "order_status", "technical_issue"]),
  confidence: z.number().min(0).max(1),
  summary: z.string().max(500),
  requestedAction: z.enum(["draft_reply", "open_ticket", "request_review"]),
});

type Decision = z.infer<typeof Decision>;

export function parseDecision(raw: unknown): Decision {
  const parsed = Decision.safeParse(raw);
  if (!parsed.success) throw new Error("MODEL_CONTRACT_VIOLATION");
  return parsed.data;
}
Validation does not prove that a decision is correct. It proves something narrower: the application will not receive an invented action name, malformed probability or unbounded payload.
Separate prediction from authorization. A model may propose open_ticket; code determines whether the action is permitted.
type ActionContext = {
  canCreateTicket: boolean;
  risk: "low" | "medium" | "high";
};

export function authorize(
  decision: Decision,
  context: ActionContext,
): "execute" | "review" | "reject" {
  if (!context.canCreateTicket) return "reject";
  if (context.risk === "high") return "review";
  if (decision.confidence < 0.75) return "review";
  if (decision.requestedAction === "request_review") return "review";
  return "execute";
}
This is less glamorous than unrestricted autonomy. It is how real systems remain governable.
An agent tool is a capability granted to probabilistic software. Treat it like an API exposed to a potentially confused operator.
A good tool is narrow, idempotent where retries are possible, authenticated independently of the model, authorized against the initiating identity, explicit about side effects, observable without leaking secrets and able to run in dry-run mode.
// Dangerous: broad scope and unclear side effects.
async function manageCustomerAccount(input: unknown) {}

// Better: one bounded operation.
async function createRefundDraft(input: {
  orderId: string;
  amountInPaise: number;
  reasonCode: "duplicate" | "damaged" | "service_failure";
  idempotencyKey: string;
}) {
  // Creates a draft. It does not move money.
}
For irreversible operations, expose a two-step protocol. prepare_action returns a human-readable diff and signed action token. commit_action accepts that token after policy or human approval. The reviewer then approves the exact operation that will execute, not a new model interpretation generated afterward.
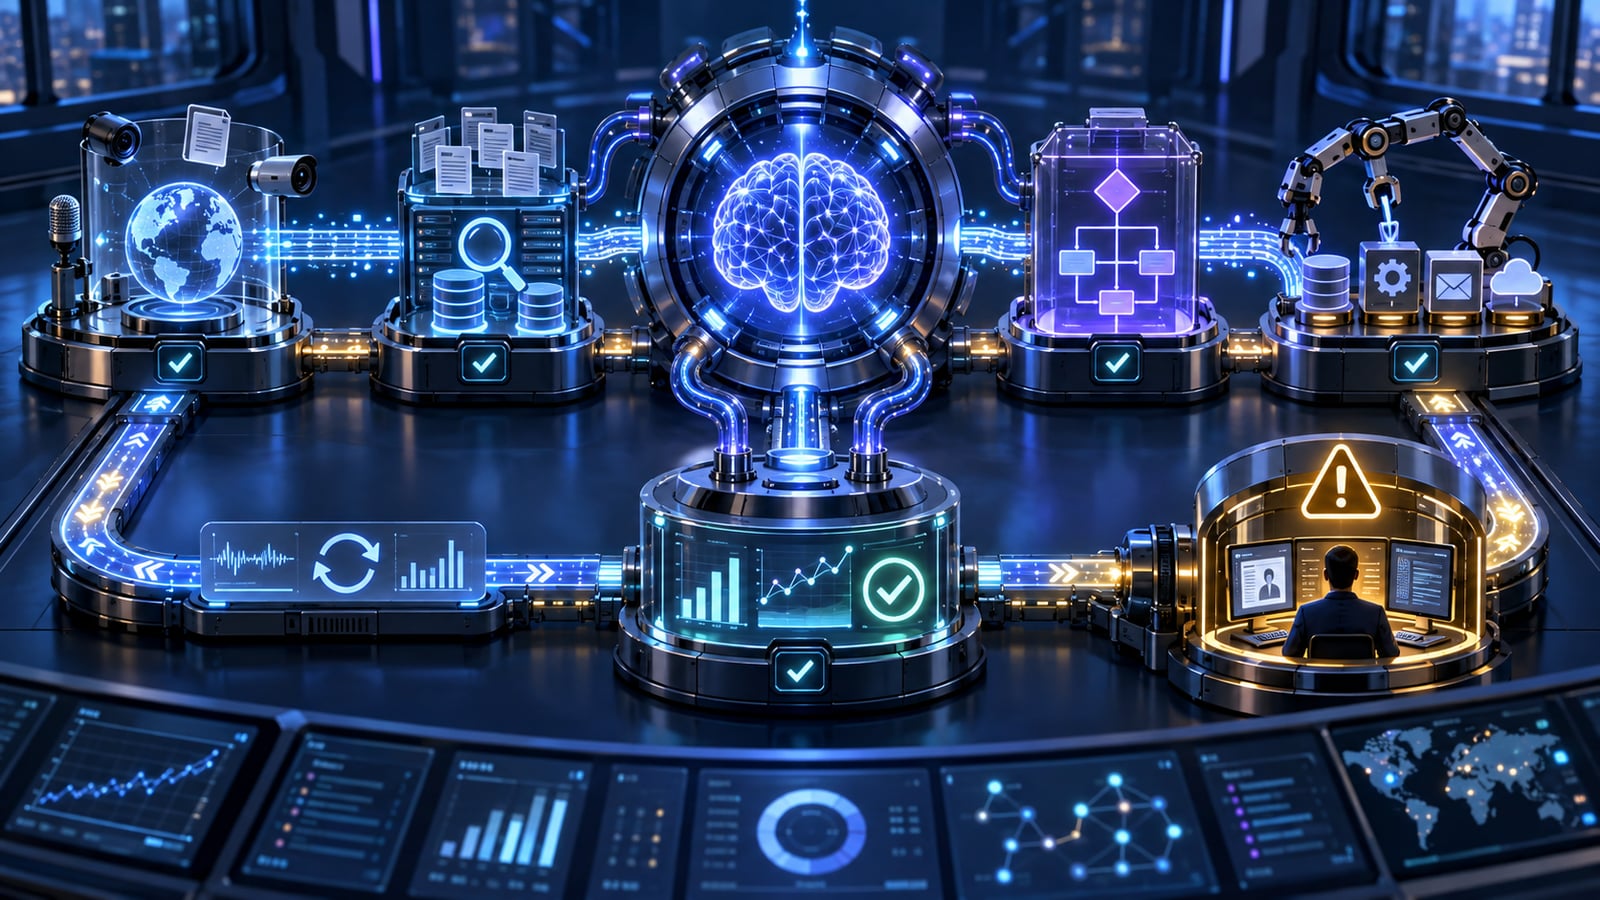
Agents loop: observe, decide, act, inspect and continue. Without limits, a transient failure can become a retry storm.
type RunBudget = {
  maxSteps: number;
  maxModelCalls: number;
  maxToolCalls: number;
  maxCostUsd: number;
  deadlineMs: number;
};

function assertBudget(b: RunBudget, u: {
  steps: number;
  modelCalls: number;
  toolCalls: number;
  costUsd: number;
  elapsedMs: number;
}) {
  if (
    u.steps >= b.maxSteps ||
    u.modelCalls >= b.maxModelCalls ||
    u.toolCalls >= b.maxToolCalls ||
    u.costUsd >= b.maxCostUsd ||
    u.elapsedMs >= b.deadlineMs
  ) throw new Error("AGENT_BUDGET_EXCEEDED");
}
Budgets should vary by task. A read-only research query can tolerate several retrieval attempts. A financial action should have a short path, low tool-call ceiling and mandatory review.
Traditional tests verify parsers, permissions and tool implementations. They do not fully test a probabilistic system whose behaviour can change when prompts, models, context or providers change.
An evaluation suite should contain representative inputs, expected outcomes, edge cases, adversarial cases, policy-sensitive cases and historical failures. Store the dataset separately from the prompt so engineers do not unconsciously tune examples to the implementation.
type EvalCase = {
  id: string;
  input: string;
  expectedIntent: Decision["intent"];
  mustEscalate: boolean;
};

const cases: EvalCase[] = [
  {
    id: "refund-explicit",
    input: "I was charged twice for order 8041. Refund one charge.",
    expectedIntent: "refund_request",
    mustEscalate: false,
  },
  {
    id: "refund-ambiguous",
    input: "The amount on my statement does not look right.",
    expectedIntent: "refund_request",
    mustEscalate: true,
  },
];
Do not collapse results into one accuracy number. Track false autonomous actions, unnecessary escalations, wrong tool selection, unsupported claims, policy violations, latency and cost regressions, and inconsistent outcomes for equivalent inputs.
The metric must match the consequence. A false positive may be tolerable for an internal tag. It can be disastrous for an account lock.
Offline evals catch regressions before release. Production traces reveal cases the suite did not anticipate.
{
  "trace_id": "tr_01K5...",
  "feature": "support_router",
  "model": "provider/model-version",
  "prompt_version": "support-router-v17",
  "decision": {
    "intent": "technical_issue",
    "confidence": 0.82
  },
  "policy_result": "execute",
  "tool": "create_support_ticket",
  "latency_ms": 684,
  "estimated_cost_usd": 0.0018,
  "outcome": "agent_resolved",
  "pii_logged": false
}
Do not let tracing become a shadow database of private prompts, credentials and customer records. Redact before telemetry leaves the request boundary, apply retention periods and record hashes when raw content is unnecessary.
Monitor distributions, not only averages. p50 latency can be stable while p99 explodes. Mean cost can hide a retry loop affecting one tenant. Overall accuracy can improve while one language or user segment deteriorates.
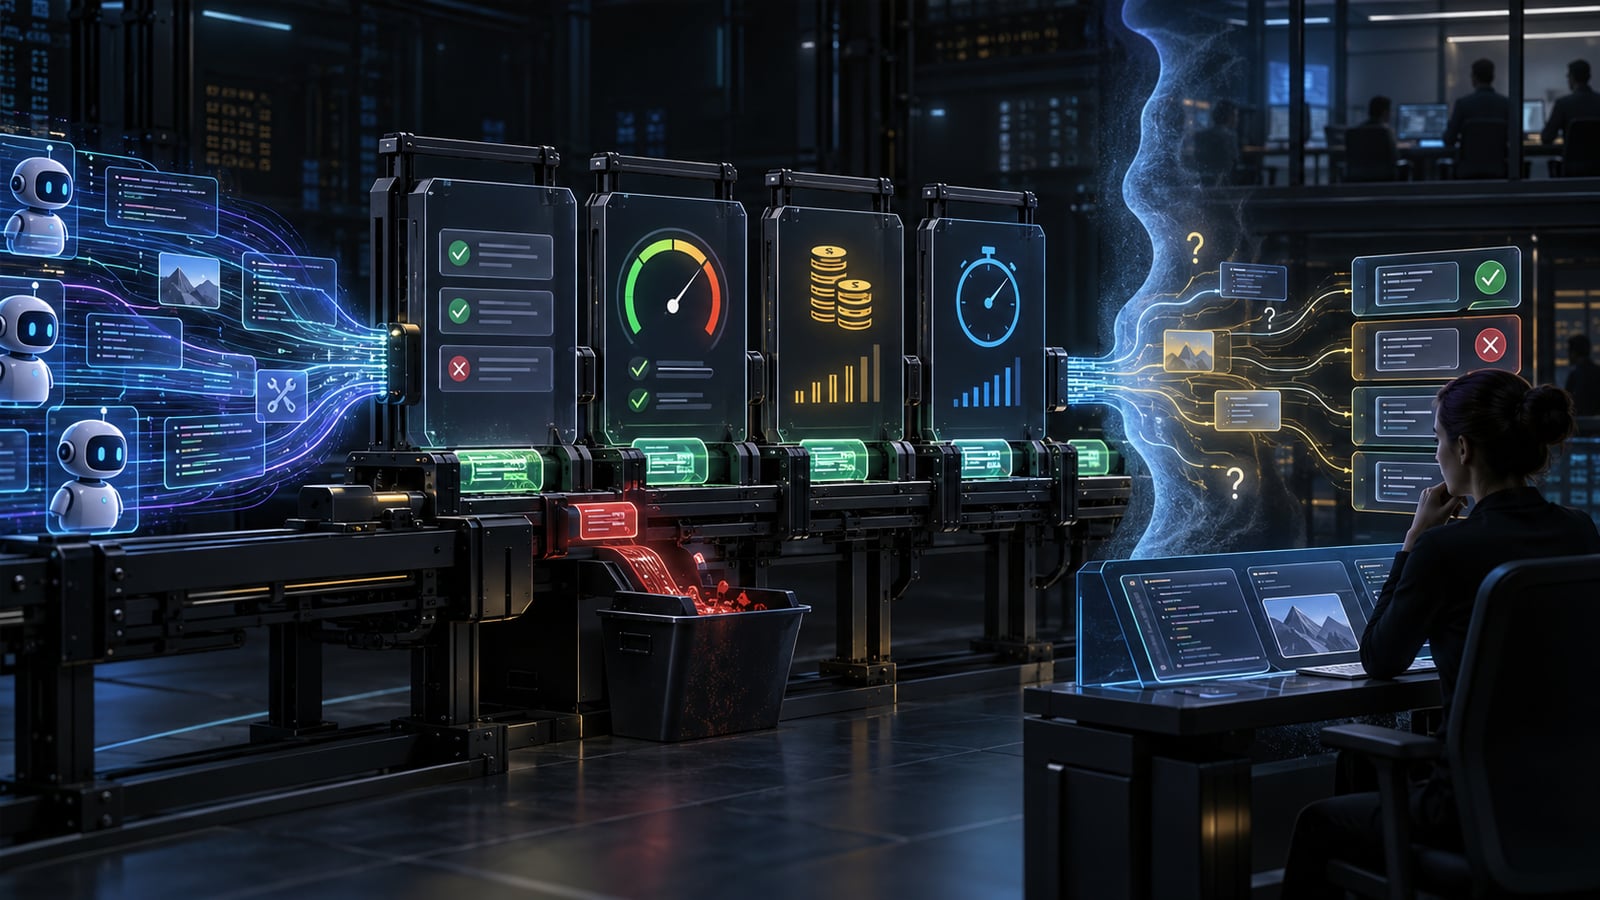
“Human in the loop” is not sufficient. A reviewer faced with hundreds of low-context approvals will click through them.
Risk tierExampleDefault controlLowApply an internal tagAutomatic with samplingMediumDraft a customer responseAutomatic draft, human sendsHighChange account accessExplicit approvalCriticalMove money or delete recordsDeterministic policy plus multi-party approval
Confidence may inform these gates, but confidence is not authorization. A model that reports 99% can still be wrong, miscalibrated or outside its evaluated domain.
Combine action risk, confidence, input completeness, anomaly signals, user permissions, reversibility and similarity to evaluated traffic.
Never point production at an unversioned “latest” model and hope for improvement. A change can alter tool selection, refusal behaviour, formatting, latency, cost and multilingual performance.
Pin versions where possible. Run offline evals. Shadow production traffic. Compare outcomes. Roll out by percentage. Keep a tested rollback path.
The same discipline applies to prompts, tool descriptions, retrieval indexes and embedding models. They are executable behaviour, even when stored as text.
Before shipping an AI workflow, require evidence for each question:
1. Are inputs, outputs and tool arguments validated? 2. Does every action execute with the initiating user's permissions? 3. Does the change pass representative and adversarial evals? 4. Which actions are automatic, reviewed or prohibited? 5. Are steps, latency, retries and cost capped? 6. Can an engineer reconstruct a failure without exposing private data? 7. Can the system fall back or roll back safely? 8. Which team owns degradation in quality or cost?
If an answer is “the model usually handles it,” the system is not ready.
Models will improve and prices will fall. That does not remove the need for boundaries, evaluation and operational ownership.
AI engineering is not prompt engineering with deployment attached. It converts probabilistic capability into a controlled service:
That is how a demo becomes infrastructure.
Comments0